Document Processing Benchmark
Why we built this. We want to evaluate how specialized document processing APIs, Frontier VLMs, and General Document Processing Platforms can help AI Agents complete difficult real world tasks where handling a document is a critical step.
In this task, we test them in a heavily redlined snapshot of a PDF document and evaluate how well they parse it in order to provide the most reliable and accurate outputs to an AI Agent that is on the receiving end of it. This directly affects any downstream task or decision that the Agent would subsequently take.
We are evaluating the parser, and not the Agent. The AI Agent harness is held constant across all cases. We are answering the question of which is the best document processor for agents and not which is the best end to end agent for document related tasks. Note that this Task does not simply test redlining capabilities of a parser. There are a number of scenarios within which redlines have been made such as tables, footers, multi page references and so on. Therefore, in order to get the Task Completed accurately, the parser must get all of them correct in addition to the redlining aspect.
Semantic understanding of parsers is measured. A parser may produce clean, fluent, confident markdown in which a deletion or insertion is not represented correctly. We test this and make sure that the semantics of the PDF are captured correctly to get a task completion point.
Partners. Reducto, LlamaIndex and Extend are partners. Partners suggest domains, help us understand which evals and benchmarks are useful to their customers, and subscribe to our evaluations on the public and validation sets. Task design, data preparation, labelling and the held-out set are not shared with or influenced by any partner.
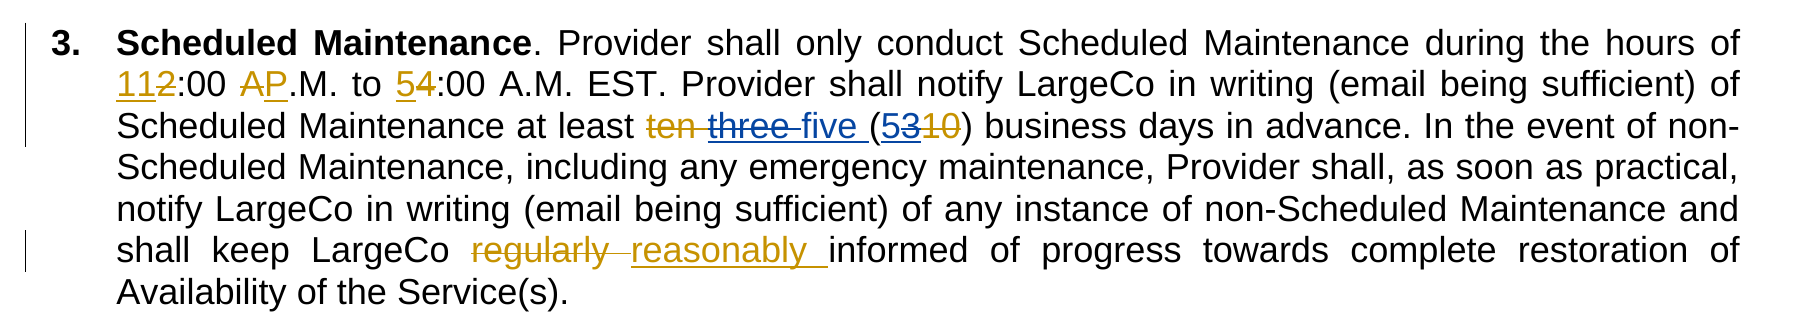
Sample task and context. This is Page 18 of a 38-page service level agreement. The notice period was negotiated down from ten days, then to three, and settled at five, each earlier number struck in place. The candidates on this benchmark receive the entire 38 page PDF of the service level agreement and give the parsed output. This is then fed to an Agent with the following Question, and if the Hidden Ground truth is answered by the Agent, then the parser did its job right.
This is the clause as it actually appears in the PDF. The struck numbers are history and the live number is five, obvious to a reader, and marked by nothing except a horizontal rule drawn across the characters and a change of colour.
question
How many business days’ advance written notice must Provider give LargeCo for Scheduled Maintenance?
hidden ground truth
Five (5) business days. Read directly from the tracked changes in the source file, with nothing hand-annotated and no vendor output in the key.
Two real parses of that page. The first kept the deletions labelled, so an agent can still tell which number is operative. The second returned the rule as nothing at all, and three rounds of negotiation collapsed into one live figure that was never agreed by anyone.
@@ a parser that kept the deletion labelledProvider shall notify LargeCo in writing (email beingsufficient) of Scheduled Maintenance at least+ ~~ten~~ ~~three~~ <u>five</u> (~~5310~~<u>5</u>)business days in advance.
@@ a parser that dropped it: every round survives as live textProvider shall notify LargeCo in writing (email beingsufficient) of Scheduled Maintenance at least- ten three five (5310)business days in advance.
The first case clearly states that 5 is the only remaining digit and others have been deleted. However, the second case just returns all digits without semantic information. This can never allow the Agent to process the underlying task correctly since the ground truth will be lost here. This is exactly what we are trying to measure here: given the same agent, and question, how correct is the parser layer in between.
2026-10-24 Extend repriced to $0.02 per page, cost columns updated. Full changelog →
Benchmark Data
Providers are listed alphabetically.
How to read this data
We segment vendors into 5 categories: specialized document parsers, long running agentic parsers, frontier VLMs, generalized document processing platforms and vendorless runs that intentionally do not represent any vendor, but rather contextualize the task and numbers.
The two vendorless runs serve the following purpose:
- Best case: every deletion is retained and is labelled
~~like this~~. The most any parser could possibly be worth on these questions. It is the Gold standard. - Baseline: the identical text with every mark removed, as though the strike had never been there. What you get from a parser that reads the words and loses the edits. This is the worst case scenario.
They help define Gap closed: where a candidate on this benchmark landed between those two, as a percentage. The baseline is 0% and the best case is 100% by definition.
The distance between those two rows represents the capability of the parser. A parser can win or lose on a redline within this range based on how good it is.
Parser $ / 1k correct is what the parser billed to parse every contract once, divided by the questions the agent then answered correctly, per 1,000. It is what you pay the parser for every 1,000 correct answers.
Total tokens / 1k correct counts every token the answering agent read and wrote, per 1,000 correct answers. Most of it is the parser's output, read again with every question.
Text-layer PDFs
The contracts as exported: the characters are in the file, and a parser can read them without looking at the page.
| Parser | Endpoint & settings | Accuracy | Gap closed | Median parse time | Parser $ / 1k pages | Parser $ / 1k correct | Total tokens / 1k correct | List price |
|---|---|---|---|---|---|---|---|---|
| Specialised document parsers | ||||||||
| Datalab convert | REST · multipart POST /api/v1/convert, polledmode: accurate, output_format: markdown | 63.9%± 3.4% | 55.7% | 24sp95 55s | $10.00 | $23.86 | 30.2M | $0.010 / pageconvert accurate, $10 per 1,000 pages, pay as you go |
| Datalab track changes | REST · multipart POST /api/v1/track-changes, polledoutput_format: markdown | 80.7%± 0.4% | 80.0% | 34sp95 50s | $10.00 | $18.89 | 25.0M | $0.010 / pagetrack changes, billed $10 per 1,000 pages, pay as you go |
| Extend | extend-ai SDK · files.upload() then parse()engine: parse_performance, advancedOptions.formattingDetection: change_tracking | 93.1%± 0.3% | 97.9% | 17sp95 26s | $20.00 | $32.73 | 22.5M | $0.020 / page2 credits/page at $0.01 per credit, pay as you go |
| LlamaParse agentic | llama-cloud SDK · files.create() then parsing.parse()tier: agentic, version: 2026-09-29 | 83.8%± 0.6% | 84.5% | 16sp95 71s | $12.50 | $22.71 | 23.9M | $0.0125 / page10 credits/page at $1.25 per 1,000 credits, starter / pro plan |
| Mistral OCR | REST · JSON POST https://api.mistral.ai/v1/ocrmodel: mistral-ocr-4-1, PDF inline as base64 | 36.9%± 0.4% | 16.8% | 15sp95 72s | $4.00 | $16.54 | 51.2M | $0.004 / pageOCR 4.1, $4 per 1,000 pages, API standard (not batch) |
| Pulse | REST · multipart POST https://api.runpulse.com/extractmodel: pulse-ultra-2, refine_options: text + tables + formatting | 48.4%± 0.4% | 33.5% | 53sp95 102s | $15.00 | $47.17 | 89.4M | $0.015 / page1 credit/page at $0.015 per credit, self serve |
| Reducto | reducto SDK · upload() then parse.run()model: r-1, formatting.include: change_tracking | 84.8%± 0.3% | 85.9% | 5sp95 12s | $10.00 | $17.97 | 26.4M | $0.010 / pager-1 parse, $10 per 1,000 pages, standard plan |
| Unstructured | REST · multipart POST /api/v2/parse, polledprofile: best, output: markdown | 27.0%± 0.2% | 2.6% | 65sp95 119s | $15.00 | $84.67 | 70.3M | $0.015 / pageParse API, $15 per 1,000 pages, pay as you go |
| Long running agentic parsers | ||||||||
| LlamaParse agentic plus | llama-cloud SDK · files.create() then parsing.parse()tier: agentic_plus, version: 2026-09-24 | 84.7%± 0.3% | 85.8% | 82sp95 138s | $56.25 | $101.17 | 24.0M | $0.05625 / page45 credits/page at $1.25 per 1,000 credits, starter / pro plan |
| Frontier models (VLMs)General models handed the same PDF and one shared prompt that does not mention strikethrough. Billed per token, not per page. | ||||||||
| Claude Fable 5.1 | Bedrock converse · document block, PDF as bytesmodel: claude-fable-5-1, shared parser prompt | 91.4%± 0.3% | 95.4% | 336sp95 470s | $109.67 | $182.99 | 20.8M | $11 / $55 per 1M tokensus. inference profile, 10% over global, Bedrock API |
| GPT-6 Astra | Responses API · input_file, PDF inline as base64model: gpt-6-astra, shared parser prompt | 61.6%± 0.4% | 52.5% | 256sp95 332s | $51.01 | $126.19 | 31.8M | $10 / $50 per 1M tokensinput / output, short context under 272k, API |
| General Document Processing Platforms | ||||||||
| Amazon Textract | TextType: HANDWRITING | PRINTEDthe only text-property field on a Block; the rest is text, geometry, confidence and relationships | N/Ano strike field in the response schema · Textract Block API reference | ||||||
| Azure Document Intelligence | DocumentStylecarries fontStyle (normal|italic), fontWeight (normal|bold), color, backgroundColor, isHandwritten; there is no strike field | N/Ano strike field in the response schema · DocumentStyle class reference | ||||||
| Google Document AI | no usable strike fielddocument.proto declares "bool strikeout = 8;" but comments it "This feature is not supported yet." | N/Ano strike field in the response schema · googleapis/document.proto | ||||||
| Reference runsNot vendors, and not for sale. They answer the identical questions, so they say what any score on this board is worth. Both are generated from the source file and set the scale that gap closed is measured against. | ||||||||
| Baseline | built from sourceall markup dropped | 25.2%± 0.4% | 0.0% | — | — | — | 72.2M | N/A |
| Best case | built from sourcestruck text kept as ~~…~~ | 94.6%± 0.0% | 100.0% | — | — | — | 19.4M | N/A |



Scanned PDFs: the same contracts delivered as images
Plenty of real documents arrive without a text layer — a scan, a photocopy, a phone picture of a signed page. So we re-rendered all 94 contracts to JPEG at 200 dpi and wrapped the images back into PDFs. Same corpus, same 1,500 questions, same answer keys, and no text layer, embedded font or structure tree left to read. A parser has to look at the pixels.
The reference runs are the control. They are generated from the source document rather than from the PDF, so a re-render should not touch them, and it does not: across every page of the corpus they move by at most 1.7%. That is the noise floor. What the vendor rows do here is the parse, not the measurement.
| Parser | Endpoint & settings | Accuracy | Gap closed | Median parse time | Parser $ / 1k pages | Parser $ / 1k correct | Total tokens / 1k correct | List price |
|---|---|---|---|---|---|---|---|---|
| Specialised document parsers | ||||||||
| Datalab convert | REST · multipart POST /api/v1/convert, polledmode: accurate, output_format: markdown | 63.9%± 3.2% | 57.5% | 50sp95 78s | $10.00 | $23.84 | 30.2M | $0.010 / pageconvert accurate, $10 per 1,000 pages, pay as you go |
| Datalab track changes | REST · multipart POST /api/v1/track-changes, polledoutput_format: markdown | 80.7%± 0.5% | 81.4% | 40sp95 52s | $10.00 | $18.89 | 25.0M | $0.010 / pagetrack changes, billed $10 per 1,000 pages, pay as you go |
| Extend | extend-ai SDK · files.upload() then parse()engine: parse_performance, advancedOptions.formattingDetection: change_tracking | 86.7%± 0.3% | 90.0% | 20sp95 30s | $20.00 | $35.14 | 24.4M | $0.020 / page2 credits/page at $0.01 per credit, pay as you go |
| LlamaParse agentic | llama-cloud SDK · files.create() then parsing.parse()tier: agentic, version: 2026-09-29 | 79.9%± 0.3% | 80.3% | 22sp95 58s | $12.50 | $23.83 | 25.1M | $0.0125 / page10 credits/page at $1.25 per 1,000 credits, starter / pro plan |
| Pulse | REST · multipart POST https://api.runpulse.com/extractmodel: pulse-ultra-2, refine_options: text + tables + formatting | 65.0%± 0.6% | 59.1% | 57sp95 125s | $15.00 | $35.17 | 30.2M | $0.015 / page1 credit/page at $0.015 per credit, self serve |
| Reducto | reducto SDK · upload() then parse.run()model: r-1, formatting.include: change_tracking | 83.9%± 0.4% | 85.9% | 7sp95 9s | $10.00 | $18.17 | 26.6M | $0.010 / pager-1 parse, $10 per 1,000 pages, standard plan |
| Unstructured | REST · multipart POST /api/v2/parse, polledprofile: best, output: markdown | 27.0%± 0.5% | 5.0% | 71sp95 127s | $15.00 | $84.46 | 70.2M | $0.015 / pageParse API, $15 per 1,000 pages, pay as you go |
| Mistral OCR | REST · JSON POST https://api.mistral.ai/v1/ocrmodel: mistral-ocr-4-1, PDF inline as base64 | N/Anot run on this corpus — on the public set it scores the same on both versions, because it rasterises and reads pixels either way and never opens the text layer | ||||||
| Long running agentic parsers | ||||||||
| LlamaParse agentic plus | llama-cloud SDK · files.create() then parsing.parse()tier: agentic_plus, version: 2026-09-24 | 74.9%± 0.6% | 73.1% | 133sp95 215s | $56.25 | $114.50 | 26.9M | $0.05625 / page45 credits/page at $1.25 per 1,000 credits, starter / pro plan |
| Frontier models (VLMs)General models handed the same PDF and one shared prompt that does not mention strikethrough. Billed per token, not per page. | ||||||||
| GPT-6 Astra | Responses API · input_file, PDF inline as base64model: gpt-6-astra, shared parser prompt | 93.4%± 0.5% | 99.5% | 248sp95 322s | $66.14 | $107.91 | 21.0M | $10 / $50 per 1M tokensinput / output, short context under 272k, API |
| Claude Fable 5.1 | Bedrock converse · document block, PDF as bytesmodel: claude-fable-5-1, shared parser prompt | N/Acould not be run — at 200 dpi the rendered pages exceed the model's input limit, and contracts in this corpus run to two dozen pages | ||||||
| Reference runsNot vendors, and not for sale. They answer the identical questions, so they say what any score on this board is worth. Both are generated from the source file and set the scale that gap closed is measured against. | ||||||||
| Baseline | built from sourceall markup dropped | 23.6%± 0.6% | 0.0% | — | — | — | 77.3M | N/A |
| Best case | built from sourcestruck text kept as ~~…~~ | 93.8%± 0.3% | 100.0% | — | — | — | 19.6M | N/A |
[02] methodology+
Scored under the version 2 protocol, October 2026: every contract parsed three times by each vendor, every question asked three times against each parse, and every answer bucketed by a model judge. Version 1, published 10 September 2026, was one parse, one ask, and token matching with a judge only for the residue. The two are not comparable and every published number names its version.
9 distinct cases make up the benchmark
Every task type is built from tracked changes in the source file, so every answer key is derived from the markup rather than annotated by hand. These distinct types test different capabilities: a deletion inside a number fails differently from a deleted clause.
- Numeral strike: a strike inside a numeral. Digits struck mid-number leave no word boundary to recover.
- Word-internal strike: a strike inside a word, which collapses into a different real word rather than into nonsense.
- Struck clause: a clause struck with nothing put back.
- Old and new side by side: superseded and replacement wording adjacent in the text, where the question is which one binds.
- Struck definition term: a term struck from a definition, which changes every downstream clause that relies on it.
- Struck table cell: a whole cell struck, where the loss is structural rather than textual.
- Mixed edits on a page: insertions and a deletion together, so the parser has to keep two kinds of markup apart.
- Proposal between rounds: what happened to a proposal across two drafts, which needs both documents read consistently.
- Stale cross-reference: renumbering that leaves a reference pointing at the wrong clause.
Source data and its transformation
Built from RedlineBench (CC-BY-4.0), a set of simulated contract negotiations marked up by trained attorneys representing each side. The tracked changes are genuine Word tracked changes and render identically to any other redline. The parties are fictional and the deals simulated; what is real is the markup, and the benchmark tests the rendering-and-parsing path, which is unaffected by whether the underlying deal was live.
- Strip comments. The attorneys' margin comments are their own reasoning, and several state the answer outright. A parser that captures annotations would hand the agent the answer, so we would be scoring annotation capture instead of strike fidelity. Comment parts, relationships, content-type overrides and in-document anchors are all removed, and a check proves no comment text survives anywhere in the file.
- Render. LibreOffice converts each stripped file to PDF. Tracked changes come through struck and coloured, the way Word draws them.
- Read the changes. Every edited clause is sorted by the shape of the edit, taken straight from the source file. Types that span a page or two drafts also record where each clause landed once printed.
- Write the questions. A model writes one question per edit from the resolved facts. It never sees any vendor's output, and it is asked to discard edits that do not change what the contract requires.
- Check. Automatic checks reject any question whose right and wrong answers turn out to be the same, or that asks about the text as text rather than about what the contract requires.
The render to PDF tests the parser
In the Word file a deletion is structured: the text is explicitly labelled as removed. Print that file to PDF and the label is gone. All that remains is a line drawn across characters that are otherwise ordinary text. Whether the distinction survives is now entirely down to the parser.
How each parser was called
Every arm was given the same thing, the contract PDF, and asked for markdown. None was handed the source Word file, which would let it read the deletion out of OOXML instead of recovering it from the page. Where a vendor ships a first-party SDK it is used rather than raw HTTP, so the arm exercises the path that vendor's own documentation puts customers on. The exact interface and settings for each arm are in the endpoint column of the board, and each parser name there links to the vendor documentation for the call.
Tracked-change handling is the one setting that is not uniform, because it cannot be: Reducto, Extend and Pulse expose it as a flag, Datalab as a separate endpoint, and LlamaParse applies it without asking. Each arm runs it the way its vendor documents. The Datalab convert arm is the exception and is on the board deliberately: it is the same vendor with no tracked-change support at all, which is what the gap between the two Datalab rows is measuring.
The frontier arms have no such flag to set, because for a general model the prompt is the flag. They receive the identical PDF and one shared instruction that asks for a faithful markdown rendering.
That prompt in full, identical for every frontier arm:
Convert this document to clean, well-structured markdown. Reproduce the page faithfully, preserving headings, paragraphs, lists, tables and inline formatting. Output only the document content, with no commentary, preamble or code fences.
What it asks for is what a document parser sells: the page, in markdown, faithfully. Whether faithfully includes the deletions is the thing under test.
How an answer is marked
Every answer is bucketed by a model judge, gpt-6-sol. It sees the question, the correct, stale and fused reference answers, and the agent's answer. It never sees the contract and is never told which parser produced the text. The answers to one question are judged together, twenty to a call, each bucketed on its own, so “the section labelled 2.2” against an expected “Section 2.2” is never marked down for phrasing. A fifth label, ambiguous, is reserved for an answer that asserts two positions at once and is counted with other.
Version 1 scored by whole-token matching against the three reference strings and sent only the residue to a judge. That match is still recorded on every row as an audit of the judge. The judge prompt was revised on 29 September after 13 of 20 sampled disagreements between judge and token match turned out to be answers marked wrong for naming a live replacement clause the reference did not mention.
Nine replicates make one score
Parser output varies between calls. A probe step parsed a few contracts repeatedly per vendor and confirmed it, so a single parse is a sample, not a measurement. Every contract is parsed three times by each vendor and every question is asked three times against each parse. An arm is scored on nine replicates and 13,500 graded answers, and accuracy is the share of all nine judged correct.
The ± on the board is the sample standard deviation of accuracy across the nine, parser noise and reader noise together. Two arms within each other's spread are tied, not ranked. The agent answering every question is gpt-6-luna in every row, with a cache breakpoint between the contract and the question; version 1 used gpt-5.6-sol.
Upper and lower bounds for this task
Baseline and Best case are not products. Both are generated from the source file rather than read off the page, and both answer the identical questions through the identical agent, so the only thing that differs between them is how much of the markup survived to reach it.
- Best case: struck text kept and labelled
~~like this~~. What a parse that lost nothing would enable. Carried asoraclein the published run files. - Baseline: the same text with every character unmarked. What happens when the strike is dropped entirely. Carried as
blindin the published run files.
Both are rendered from the source file, so they are parsed once and asked three times. Together they set the scale. Gap closed is (arm − baseline) / (best case − baseline), which rescales accuracy onto the range a parser can actually occupy.
Why isn't the best case 100%?
Because a perfect parse does not make a perfect reader. That row hands the agent every deletion clearly labelled and it still gets 81 of 1,500 questions wrong. About half of those are simply wrong in a way the markup does not explain, and 23 where it answered from text that was visibly marked as struck. That residual is the agent's own error rate rather than any parser's, and it is the same agent in every row.
This is exactly why the board reports gap closed next to accuracy. The reachable range on these questions is 25.2% to 94.6%, not 0 to 100, so scoring 93.1% sits far closer to the best case than the raw number suggests. Reading accuracy against 100% would credit every parser for the questions no parser can lose, and blame it for the ones no parser can win.
Cost details
Each document is parsed three times per arm, and every parse is billed. The money columns on the board are per pass, one parse of the corpus and one answer per question, averaged over the threeparses, so parser $ per page and per correct answer mean the same thing here as on the version 1 board. Questions against an already-parsed document are free to the vendor. The contract sits at the front of the agent's prompt, identical across all questions on that parse, so only the first call pays to write the cache and the rest read it. Where the API reports usage it is taken from there (Datalab), where it bills in credits from credits consumed (Extend, Pulse), otherwise from the list price per page, and from token list prices for the frontier models. Reader and judge cost are kept separate from vendor cost and neither is in the parse column.
The parse cost column is the measured cost per 1,000 pages. Contracts here differ a lot in length, and vendors price by the page, so a per-document figure would mostly measure how long the contracts are.
Agent cost is excluded from the parse column and is not uniform across arms: a verbose parser costs more to read, independently of whether it read correctly. That cost is on the board as Total tokens / 1k correct: the input and output tokens the answering agent used across every question, divided by correct answers. Parser $ / 1k correct does the same for the parse bill, so a parser that is cheap per page but leads to wrong answers shows what it really costs.
Why three large document processing platforms could not be benchmarked
Amazon Textract, Azure Document Intelligence and Google Document AI are the document services most enterprises already pay for, so their absence needs an answer. It is not that they score badly. It is that none of them has anywhere to put the result: a strike is a property of a character, and in all three response schemas a character has no such property. A benchmark score would only restate what each vendor's own API reference already says, so we cite that instead. The schema field and its reference are on the board in [01] evidence.
Azure was run end to end before being ruled out, because a schema gap and a real output are different kinds of evidence. Asked for markdown, it returned the contract in full and marked none of the deletions.
best case at least ~~ten three~~ five (5~~310~~) business daysazure at least ten three five (5310) business days
Questions about this benchmark
Why is the parser under test rather than the agent?
Every question is answered by the same agent with the same prompt. The only thing that changes between arms is the markdown the parser produced, so a difference in score is attributable to the parser. The best-case and baseline runs bound what any score can mean: same corpus, same questions, same agent, differing only in whether the strike survived.
Why does dropping the markup entirely still score 25.2%?
Because roughly 25% of these questions can be answered from context the strike does not touch. The surviving clause says enough on its own. That is exactly why raw accuracy is the wrong headline number and the board also reports how much of the gap between the baseline and the best case each parser closed.
What is the best document parser for contracts with tracked changes?
On this run Extend leads at 93.1% accuracy, closing 98% of the gap between a perfect parse and no markup at all. It is also the most expensive specialised document parser on the board at $20.00 per 1,000 pages, so it is not automatically the right pick.
Is the answer key derived from vendor output?
No. Every key is read directly from the tracked changes in the source Word file before any vendor sees anything. No vendor output appears in the key, and the judge that buckets every answer is never told which parser produced an answer.
[04]Document processing guides and comparisons: Go Deeper
+
Document parsing: Best Document Parsing APIs → · Best Document Parser APIs → · Best Document Parsing Tools → · Best Document Parser Tools → · Best Document Parsing Software → · Best Document Parser Software → · Best AI Document Processing APIs → · Best AI Document Processing Tools → · Best AI Document Processing Software → · Best Document Processing APIs → · Best Document Processing Tools → · Best Document Processing API Comparison → · Best Document Parser API Comparison → · Best Document Parsing API Comparison → · Best PDF Parsing API Comparison → · Best Intelligent Document Processing Tools & Software → · Best IDP Platforms → · Best OCR Document Parsing APIs → · Best OCR APIs → · Best OCR Tools → · Best OCR Document Parsing Tools & Software → · Best PDF OCR Software → · Best PDF Data Extraction APIs → · Best PDF Data Extraction Tools → · Best PDF Data Extraction Software → · Best PDF to Markdown APIs → · Best PDF to Markdown Converters & Tools → · Best PDF to Markdown Software → · Best PDF to JSON APIs → · Best PDF to JSON Extraction Tools → · Best PDF Parsing APIs → · Best PDF Parser Tools → · Best LLM-Ready Document Parsers → · Best Document Parsing APIs for Complex PDFs → · Best Document Parser APIs for Complex PDFs →
RAG pipelines: Best Document Parsing APIs for RAG → · Best Document Processing APIs for RAG → · Best Document Parser APIs for RAG → · Best AI Document Processing APIs for RAG → · Best OCR APIs for RAG → · Best PDF Data Extraction APIs for RAG → · Best PDF Parsing APIs for RAG → · Best PDF to Markdown APIs for RAG → · Best LLM-Ready Document Parsers for RAG → · Best Document Parsing Tools for RAG → · Best Document Parser Tools for RAG → · Best Document Parsers for Legal RAG → · Best Document Parsers for Scanned-Document RAG →
Legal documents: Best Document Parsing APIs for Legal Documents → · Best Document Parser APIs for Legal Documents → · Best Document Parsing Tools for Legal Documents → · Best Document Parser Tools for Legal Documents → · Best AI Document Processing APIs for Legal Documents → · Best AI Document Processing Tools for Legal Documents → · Best Intelligent Document Processing Tools for Legal Documents → · Best OCR APIs for Legal Documents → · Best PDF Data Extraction APIs for Legal Documents → · Best PDF to Markdown APIs for Legal Documents → · Best PDF to JSON APIs for Legal Documents → · Best PDF Parsing APIs for Legal Documents → · Best PDF Parser Tools for Legal Documents → · Best LLM-Ready Document Parsers for Legal Documents → · Best Parsers for Complex Legal Documents →
Legal contracts: Best Document Parsing APIs for Legal Contracts → · Best Document Parser APIs for Legal Contracts → · Best AI Document Processing APIs for Legal Contracts → · Best Intelligent Document Processing Tools for Legal Contracts → · Best OCR APIs for Legal Contracts → · Best OCR Tools for Legal Contracts → · Best PDF Data Extraction APIs for Legal Contracts → · Best PDF to Markdown APIs for Legal Contracts → · Best PDF Parsing APIs for Legal Contracts → · Best LLM-Ready Document Parsers for Legal Contracts →
Scanned documents: Best Document Parsing APIs for Scanned Documents → · Best Document Parser APIs for Scanned Documents → · Best AI Document Processing APIs for Scanned Documents → · Best OCR APIs for Scanned Documents → · Best OCR Tools for Scanned Documents → · Best PDF Data Extraction APIs for Scanned Documents → · Best PDF to Markdown APIs for Scanned Documents → · Best PDF Parsing APIs for Scanned Documents →
Redlined contracts: Best Document Parsing APIs for Redlined Contracts → · Best Document Parser Tools for Redlined Contracts → · Best OCR APIs for Redlined Contracts → · Best PDF Data Extraction APIs for Redlined Contracts → · Best PDF Parser APIs for Redlined Contracts →
By accuracy: Best Document Parsing APIs by Accuracy → · Best AI Document Processing APIs by Accuracy → · Best OCR APIs by Accuracy → · Best PDF Data Extraction APIs by Accuracy → · Best PDF to Markdown APIs by Accuracy → · Best PDF Parsing APIs by Accuracy →
By latency: Best Document Parsing APIs by Latency → · Best OCR APIs by Latency → · Best PDF Data Extraction APIs by Latency →
By cost: Best Document Parsing APIs by Cost → · Best PDF Data Extraction APIs by Cost → · Best PDF Parsing APIs by Cost → · Best Document Parsers for RAG by Cost →
Alternatives: LlamaParse Alternatives → · Reducto Alternatives → · Unstructured Alternatives → · Docling Alternatives → · Mistral OCR Alternatives → · LandingAI Alternatives → · Amazon Textract Alternatives → · Azure Document Intelligence Alternatives → · ABBYY Alternatives → · Nanonets Alternatives →
[05] changelog+
Every list price now names the pricing plan it comes from, and every vendor is priced on that one plan. Datalab track changes is listed at $0.010 per page, the rate Datalab billed for every track changes request, instead of $0.006, which was the track changes add-on alone. No cost column changed.
Extend lowered its price per credit from $0.0125 to $0.01, so a page now costs $0.02 instead of $0.025. Parsing is unchanged: the same pages use the same 2 credits each, so Extend was not re-run. Its cost columns were recomputed from the credits recorded on every parse. Accuracy, rankings and every other vendor are unchanged.
- Every contract is now parsed 3 times and every question asked 3 times against each parse, so each parser is graded on 13,500 answers and accuracy is reported with its standard deviation across the 9 replicates.
- The reader is now
gpt-6-luna, and a separate judge,gpt-6-sol, grades every answer. Exact token matching is still stored per answer so the judge can be audited. - Repeat parses bypass each vendor's own result cache, so the 3 parses are 3 real parses.
- Rebenchmarked every vendor on its newest release, including new versions of Extend, Reducto (r-1) and LlamaParse agentic (2026-09-29).
- Added Unstructured (Parse API,
profile=best).
- Rebenchmarked LlamaParse agentic and agentic plus on their 2026-09-24 builds.
- Rebenchmarked Reducto on its newer r-1 model.
Published the document processing benchmark: 1,500 questions on 94 redlined contracts, scored on tagged PDFs and on the same contracts re-rendered as image-only scans.